Beacon was the capstone of Palantir's American Tech Fellowship (Frontiers), May to July 2026, built on Foundry. It is a workbench for a corporate development team sourcing boutique advisory firms as acquisition targets. It has since been ported to Postgres, TypeScript and Cloudflare Workers behind the same frontend, and runs live on a synthetic universe of 700 firms that resets every night.
The problem it takes on is the stretch between a thesis and a short list a team can defend. Sources disagree, gaps get filled by hand, most firms are passed on, and the reasons for passing are written once and never used again. An AI that fills the gaps by guessing makes the list harder to defend, not easier. So Beacon's rule is that every value it shows carries the sentence it came from, and when no source has the answer, it says so.
What it does
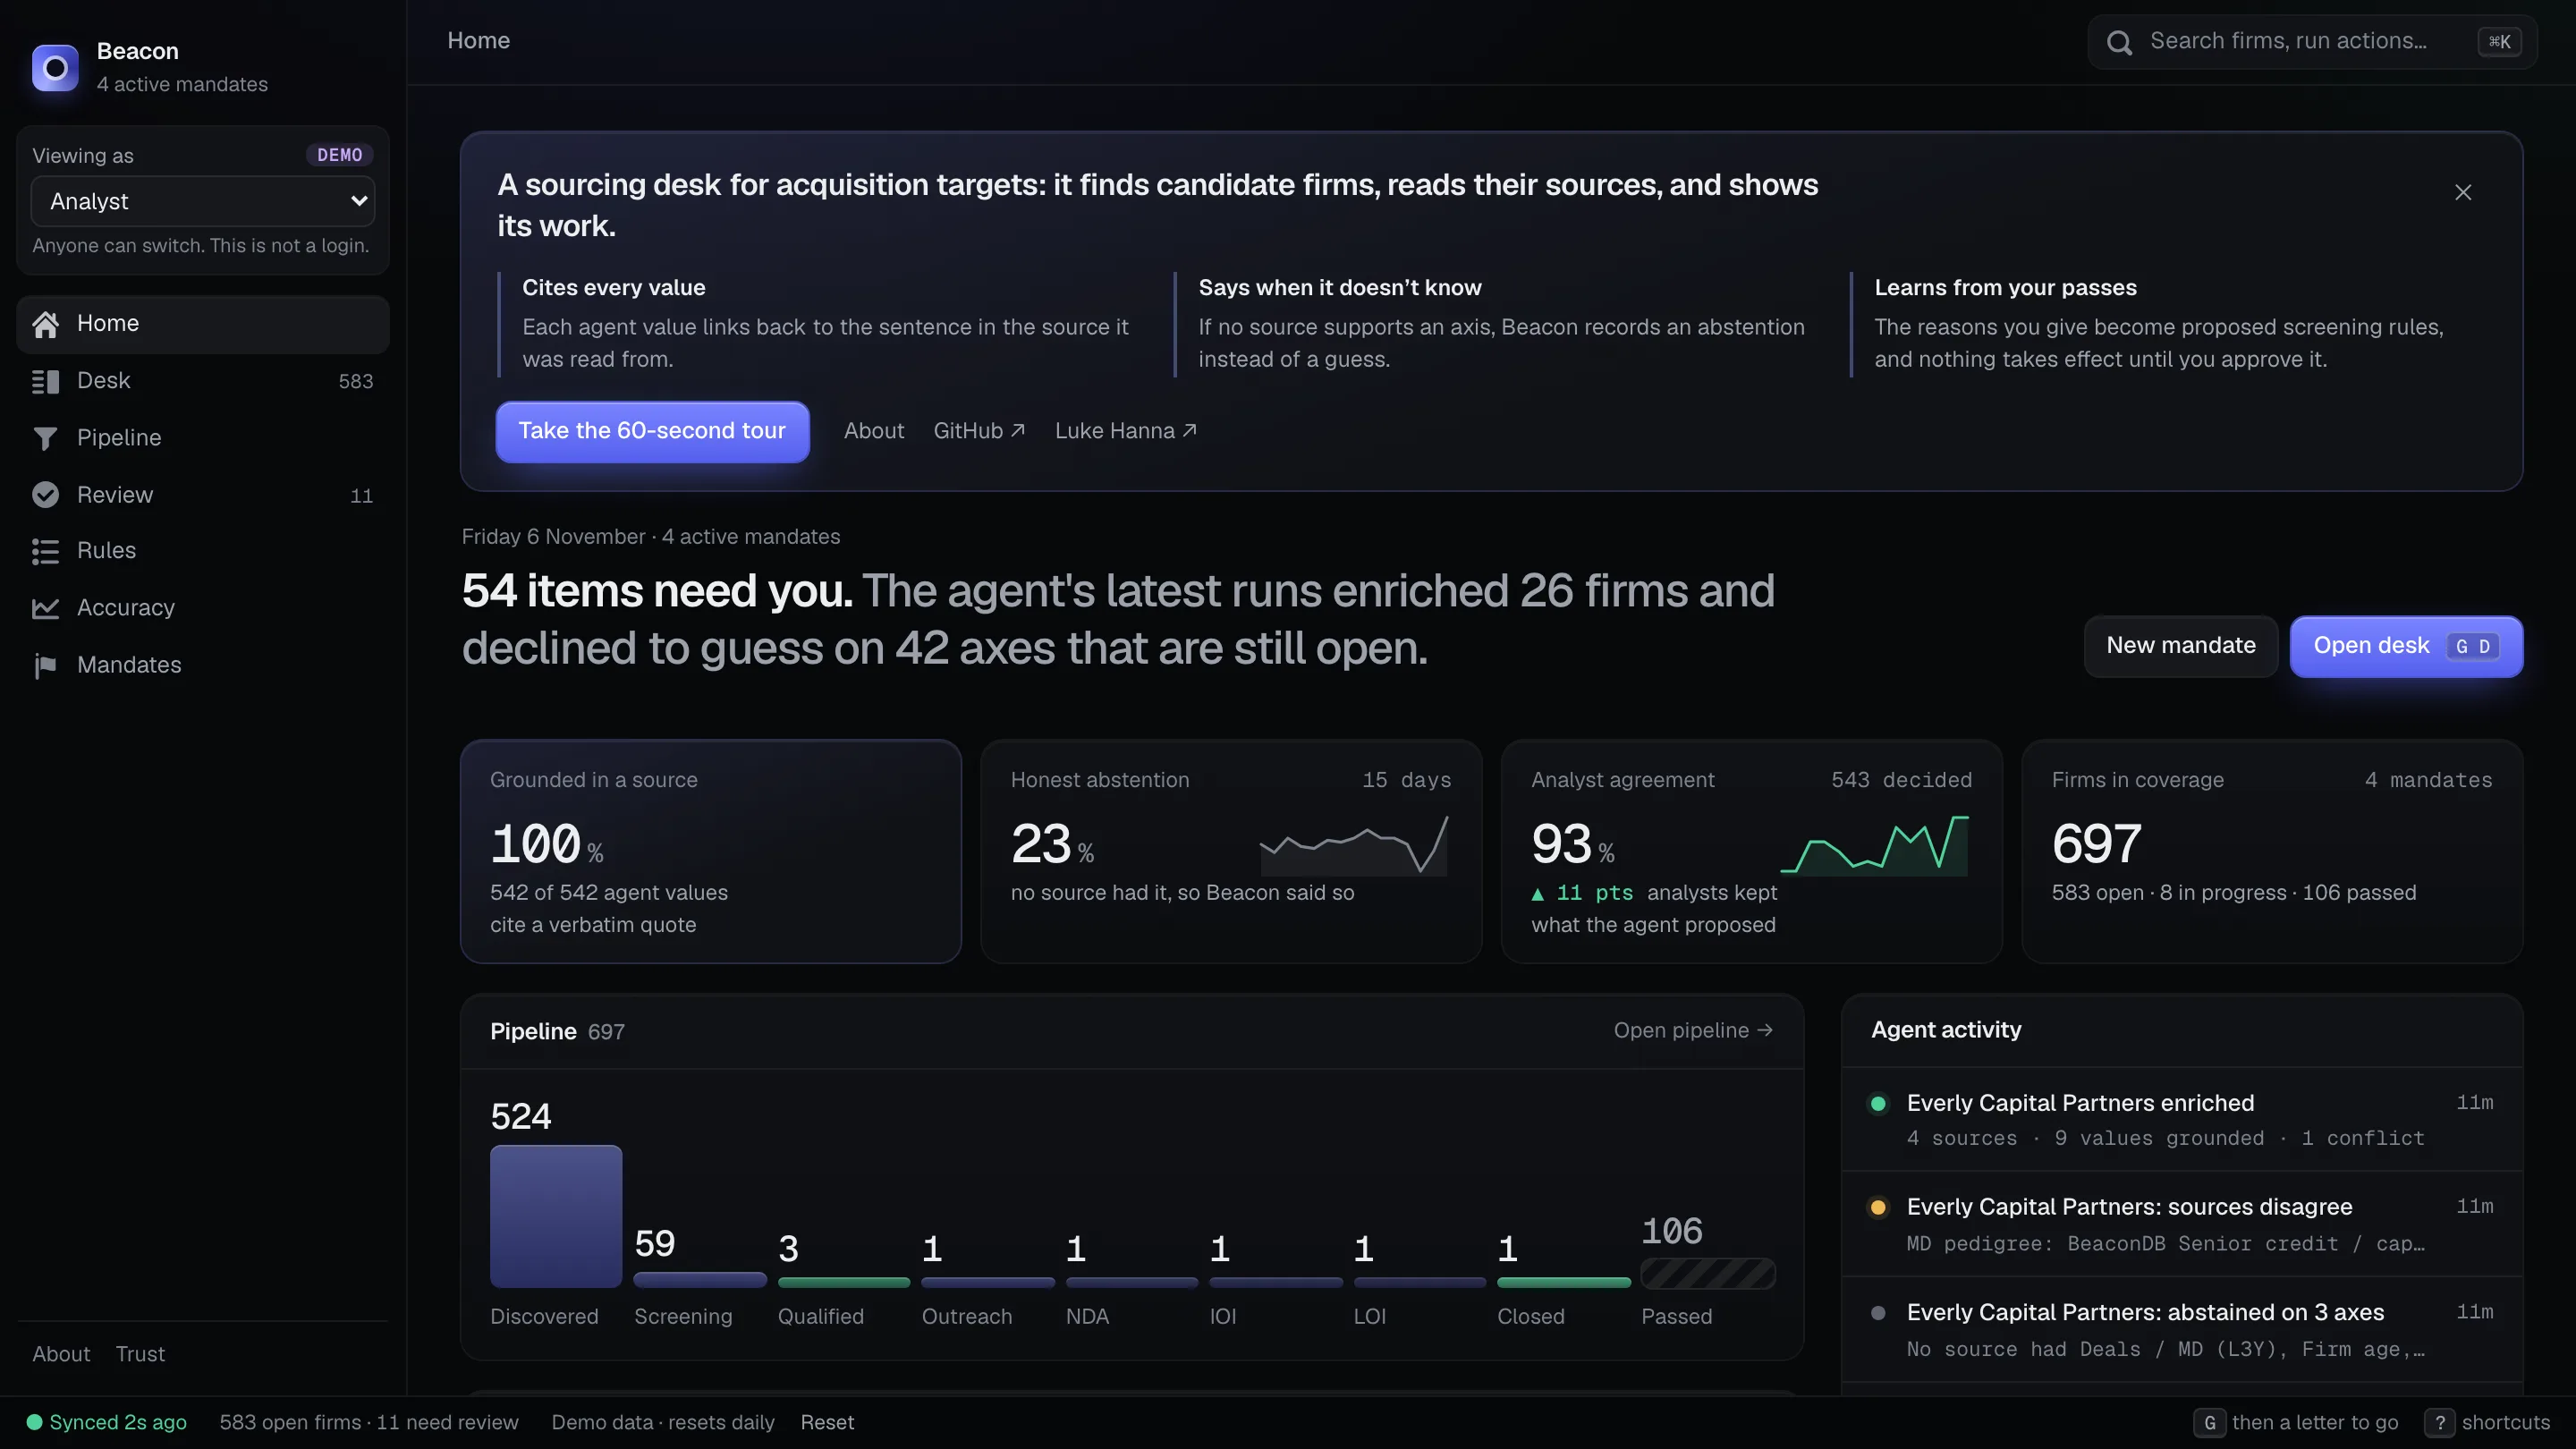
A mandate states a thesis in plain language: a kind of firm, a geography, a product, a sector. Beacon reads it back as filters, and the search yields a candidate universe. Each firm then moves through a deal funnel, Discovered, Screening, Qualified, Outreach, NDA, IOI, LOI and Closed, with Passed as the other way out.
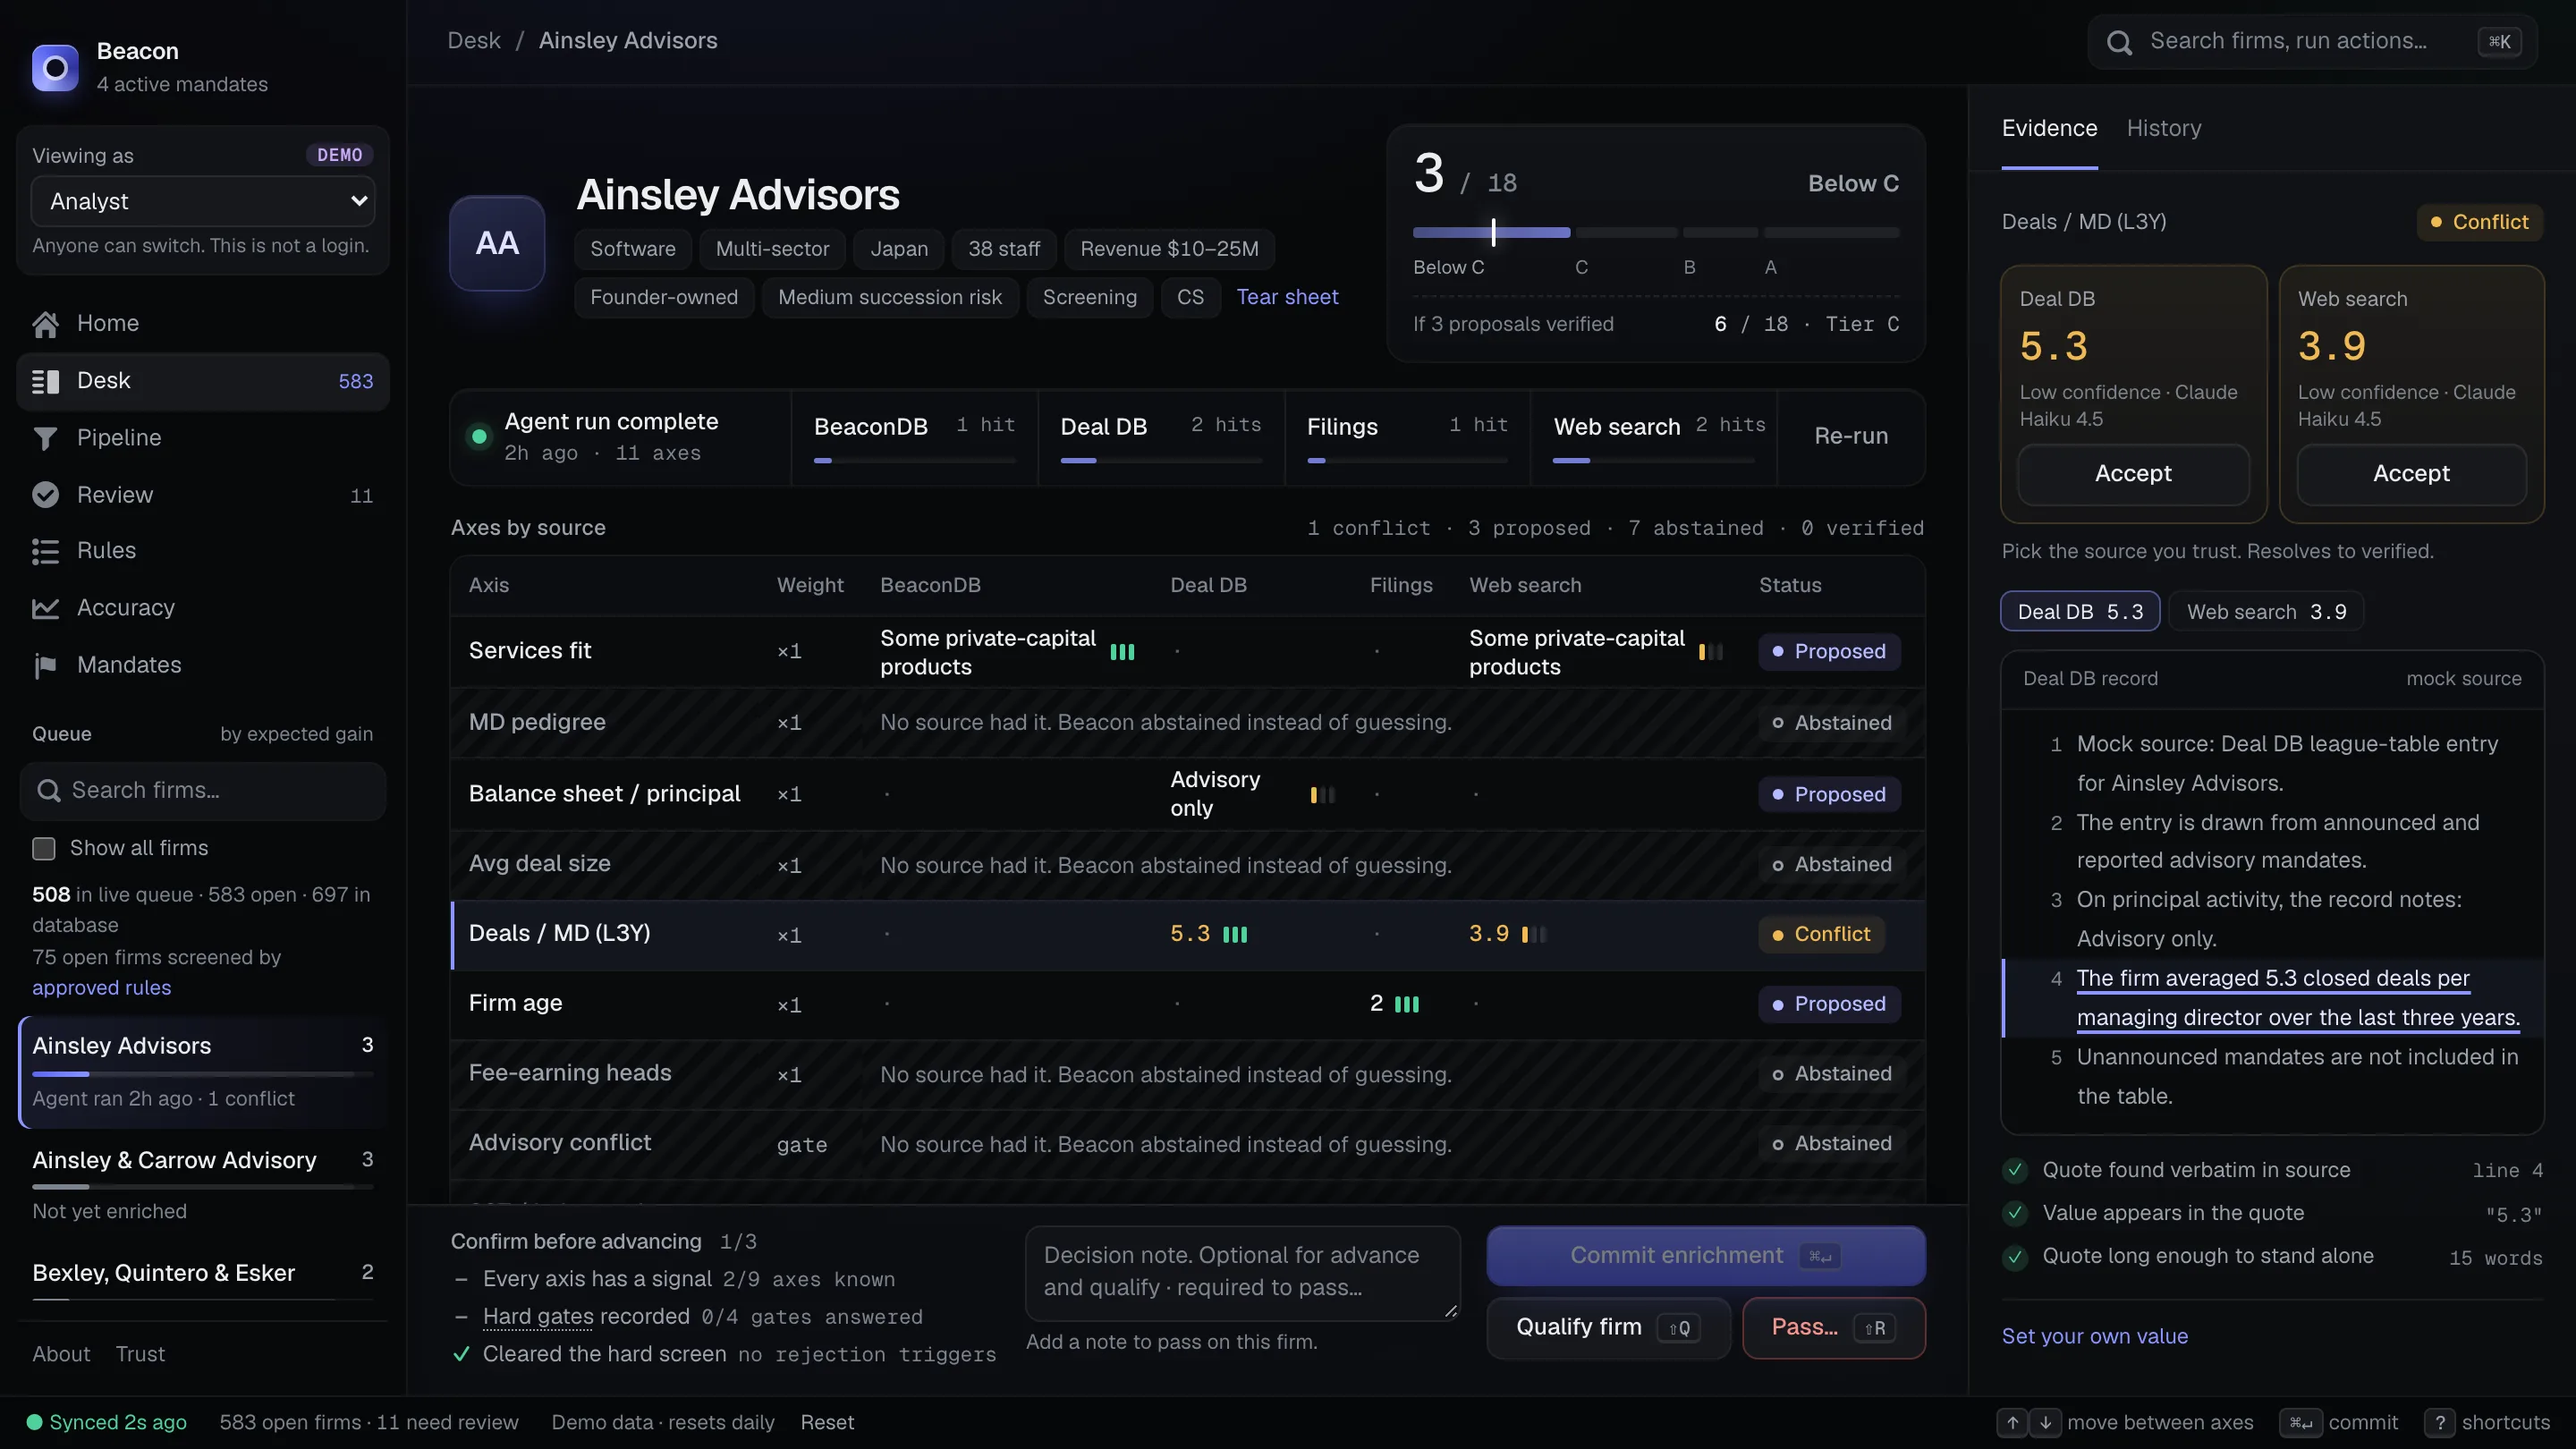
Between Discovered and a decision sits the enrichment desk. An agent proposes a value for each scoring axis from four source records; the analyst verifies or overrides them, reads the rubric score they imply, and makes the call. Passing needs a written reason, and those reasons are where the system learns.
The home page is a start-of-day page rather than a dashboard: every card and number links to the surface that does the work.
Evidence that quotes its source
Claude Haiku 4.5 reads each firm's four source records and returns every value with the exact sentence that supports it. A value survives only if the quote appears word for word in the record and contains the value. A reconciliation step then has three outcomes, and never picks a winner in a conflict: no source has it, and the axis is an abstention; the sources agree, and it is one proposed finding; they disagree, and the analyst sees both.
The extraction for all 700 firms ran once through the Message Batches API and was committed as fixtures, so the demo, the seed and CI need no API key. It cost $1.39, and 6,455 of the 6,472 values it returned passed the grounding check.
Because the universe is generated, every firm has a hidden true value for every axis, and the agent's work can be scored exactly. npm run eval does that on every CI run and fails below its floors. None of these figures says how the agent would do on real firms.
| Measure, against synthetic truth | Value |
|---|---|
| Settled values that match the truth | 93.2%, on 68.3% of axes |
| Conflicts where the more trusted source was right | 90.8% |
| Abstentions where no source had the value | 100% |
| Planted rejection patterns recovered as rules | 4 of 4 |
| Provider | Coverage | Precision |
|---|---|---|
| BeaconDB, most trusted | 25.8% | 98.5% |
| Deal DB | 70.9% | 97.1% |
| Filings | 54.4% | 95.2% |
| Web search, least trusted | 51.1% | 82.3% |
The rubric
Nine axes, each scored 0 to 2, for a maximum of 18. Two models share six axes and differ on three: corporate-finance firms are read on coverage model, services and managing-director experience; capital-solutions firms on balance sheet, services fit and managing-director experience. Tiers are A, B and C, with hard rejects above the score: a generalist coverage model or conflicted services on one side, an advisory conflict or a firm that invests its own balance sheet on the other.
One module computes the score. The server records with it and the desk previews with it, so the two cannot drift.
Rules grounded in passes
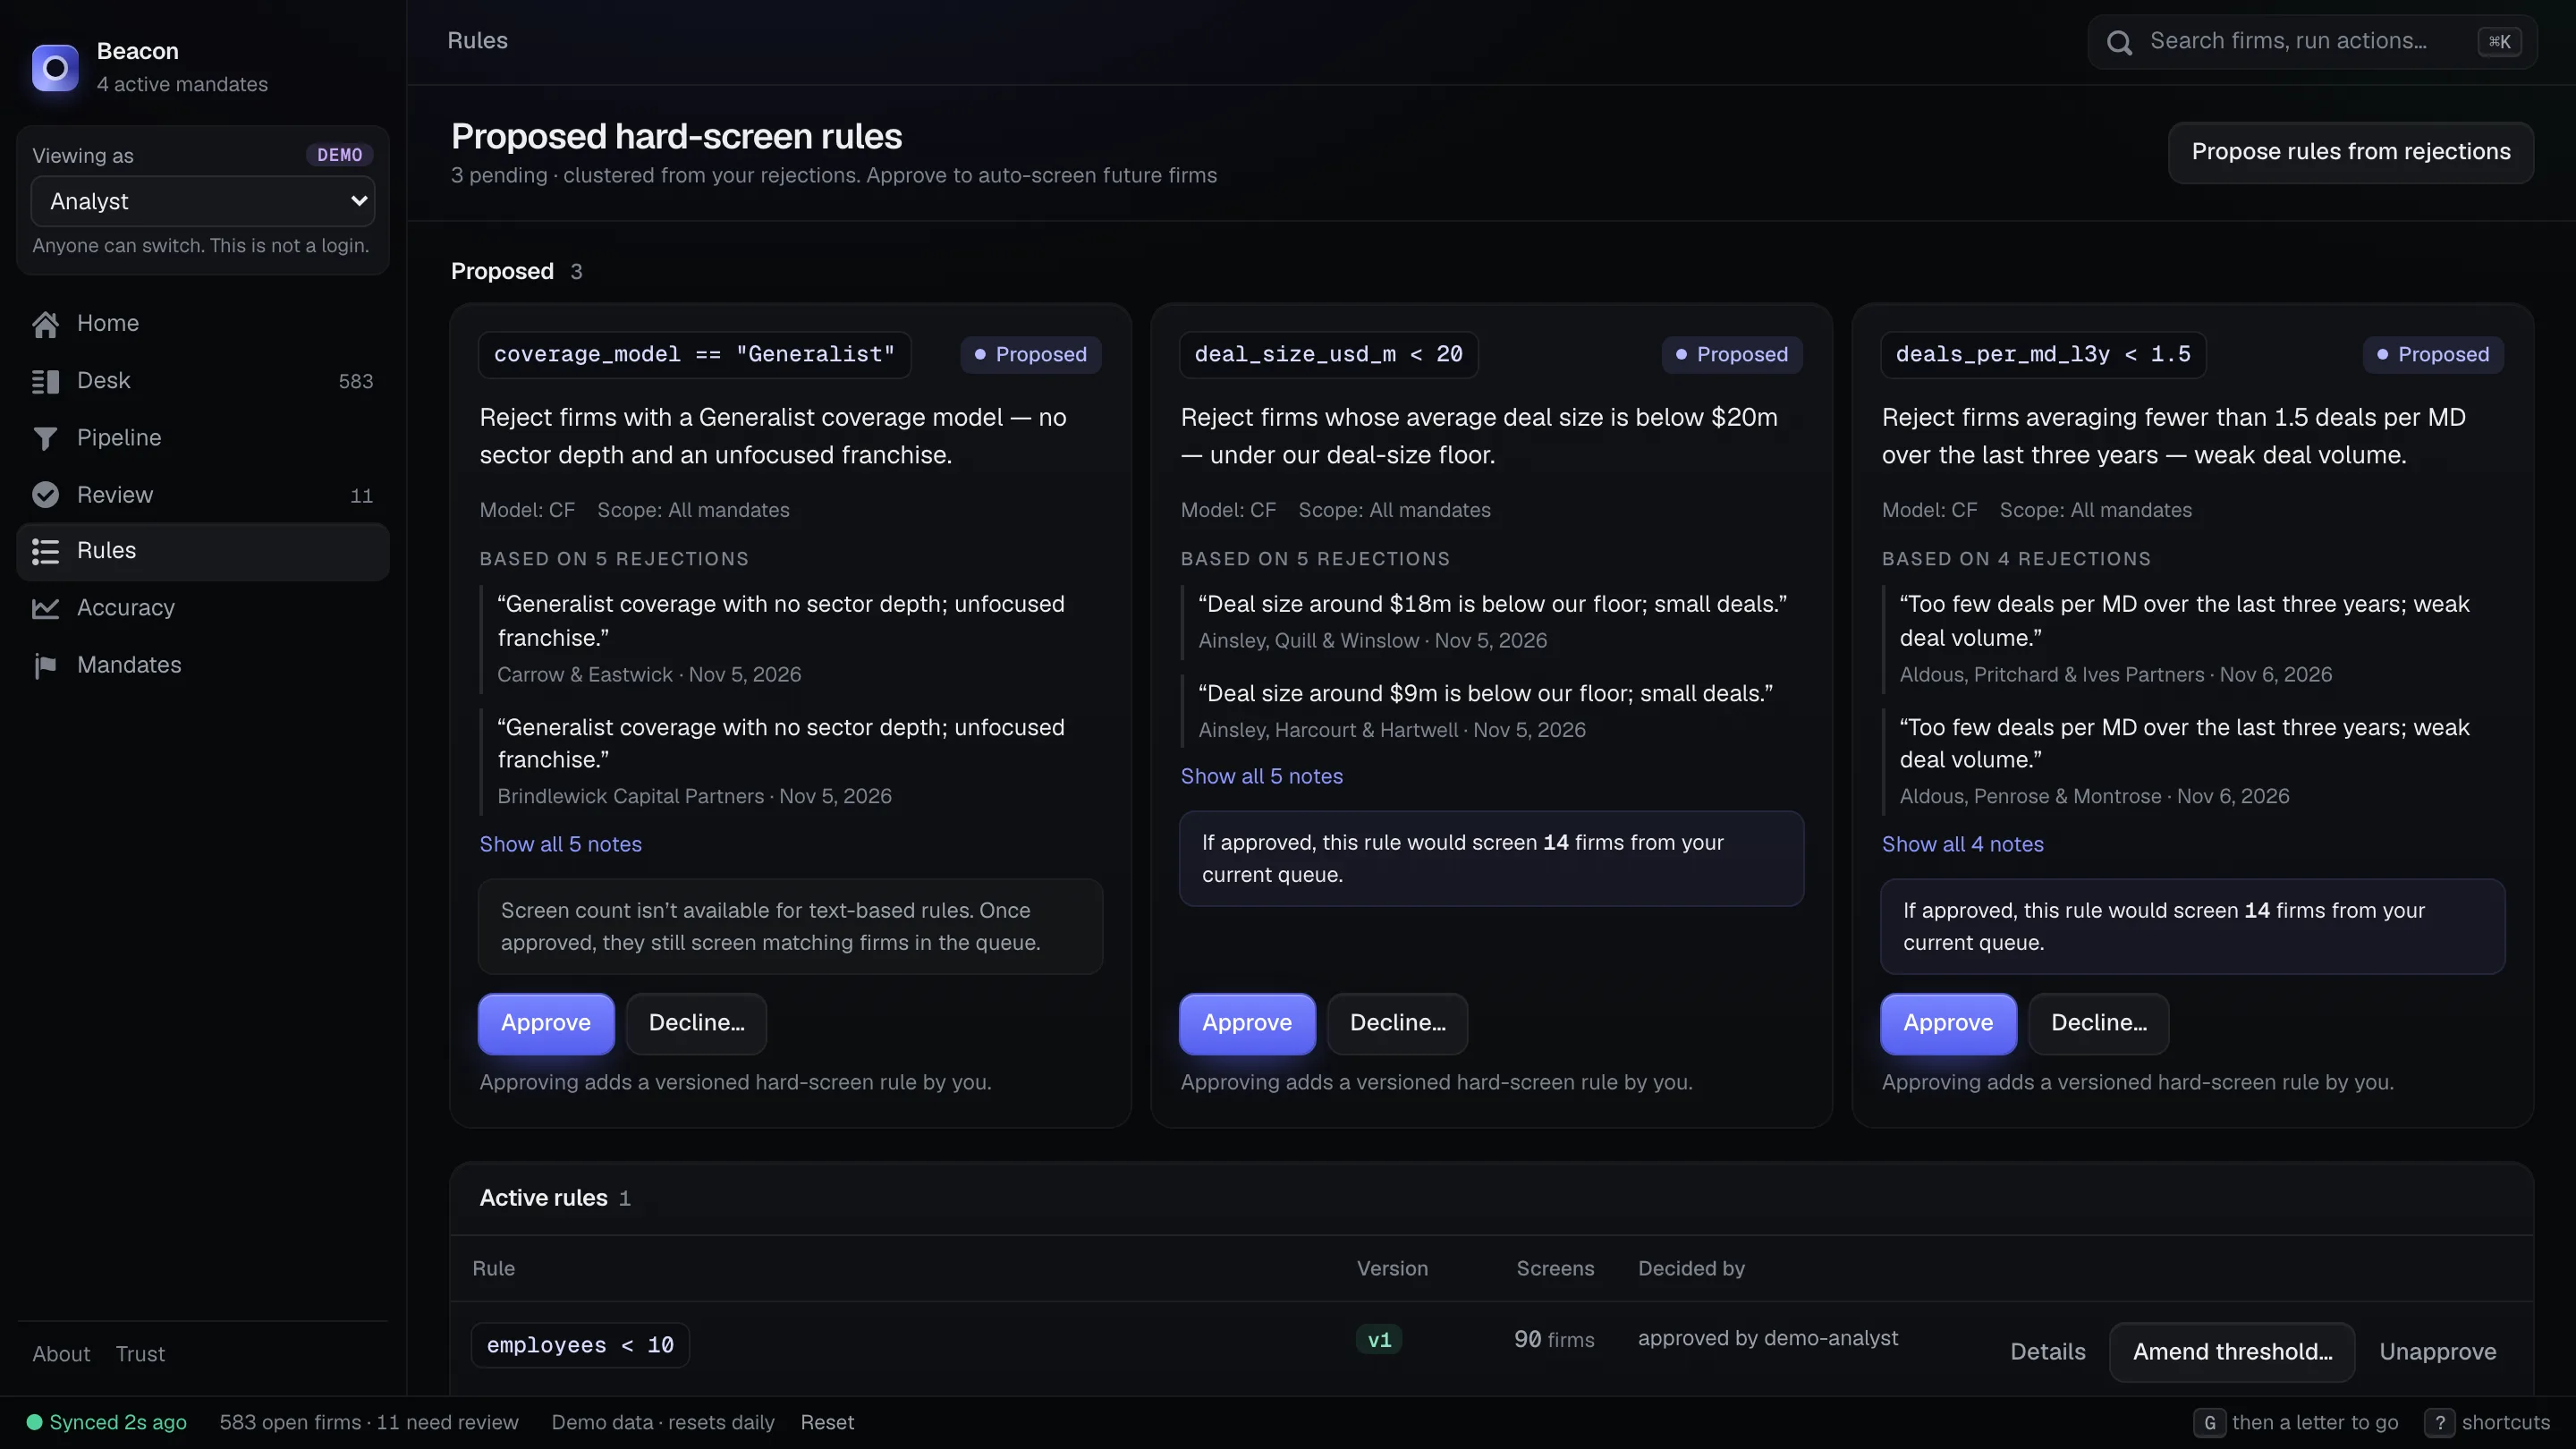
A pass carries a reason. Reasons are clustered into candidate rules of the form axis, operator, threshold, by Claude when it is enabled and by a keyword heuristic otherwise. A candidate counts a pass as support only if that firm actually satisfies the predicate, and it needs at least four distinct firms. Each proposal quotes the notes behind it and says how many firms it would screen, and nothing applies until an analyst approves it.
Unknown is not a failure. It is the reason the firm is on the desk at all.
Drift and market signals
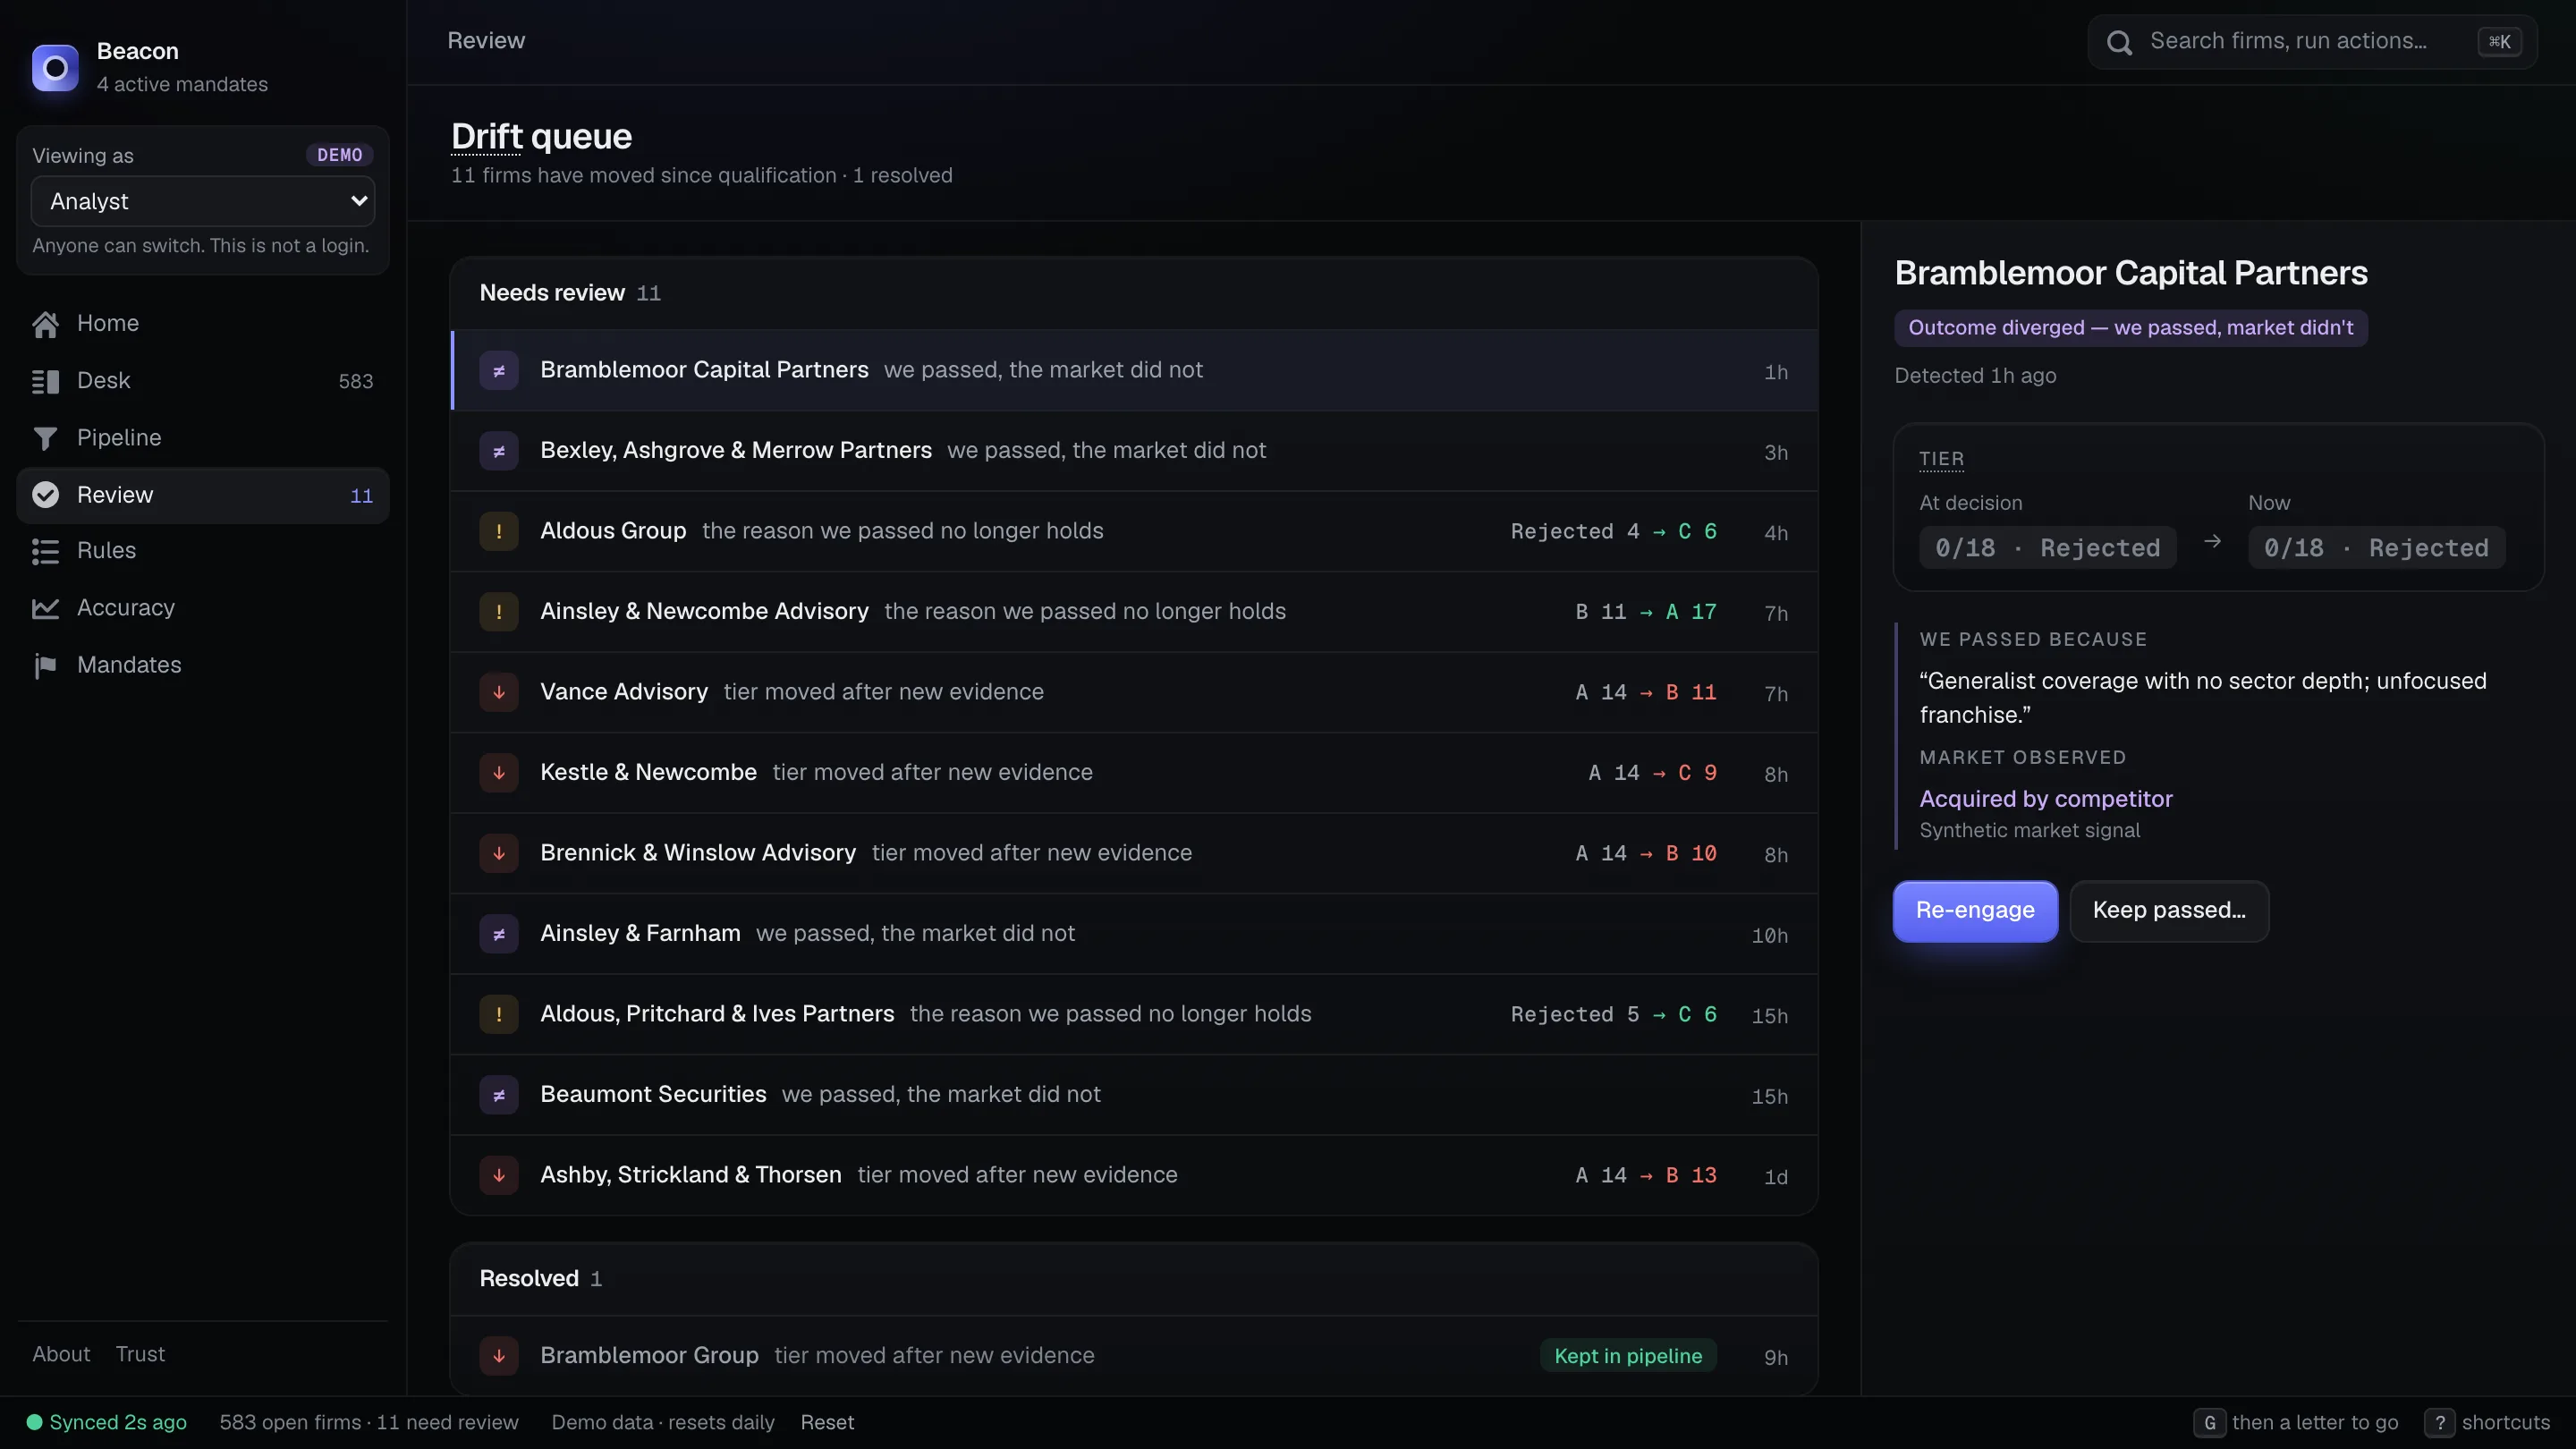
Every decision snapshots the score it was made on. New evidence rescores the firm, and so do synthetic market signals: invented news (a senior hire, a departure, a deal announcement, an acquisition) that an hourly job applies as it comes due, labelled as synthetic wherever it appears. A qualified firm drifts on any tier change; a passed firm drifts when it improves, because the reason for passing may no longer hold; a passed firm bought by a competitor raises an outcome-diverged event. Review resolves each one by re-engaging the firm or keeping it passed, with a reason.
Work that leaves the tool
The finance track turns the desk's work into things a deal team uses elsewhere, each carrying the same citations:
- Exports. An Excel workbook with a Targets sheet and a Citations sheet, and CSVs in Salesforce, DealCloud and Affinity layouts. Cells that look like formulas are neutralised.
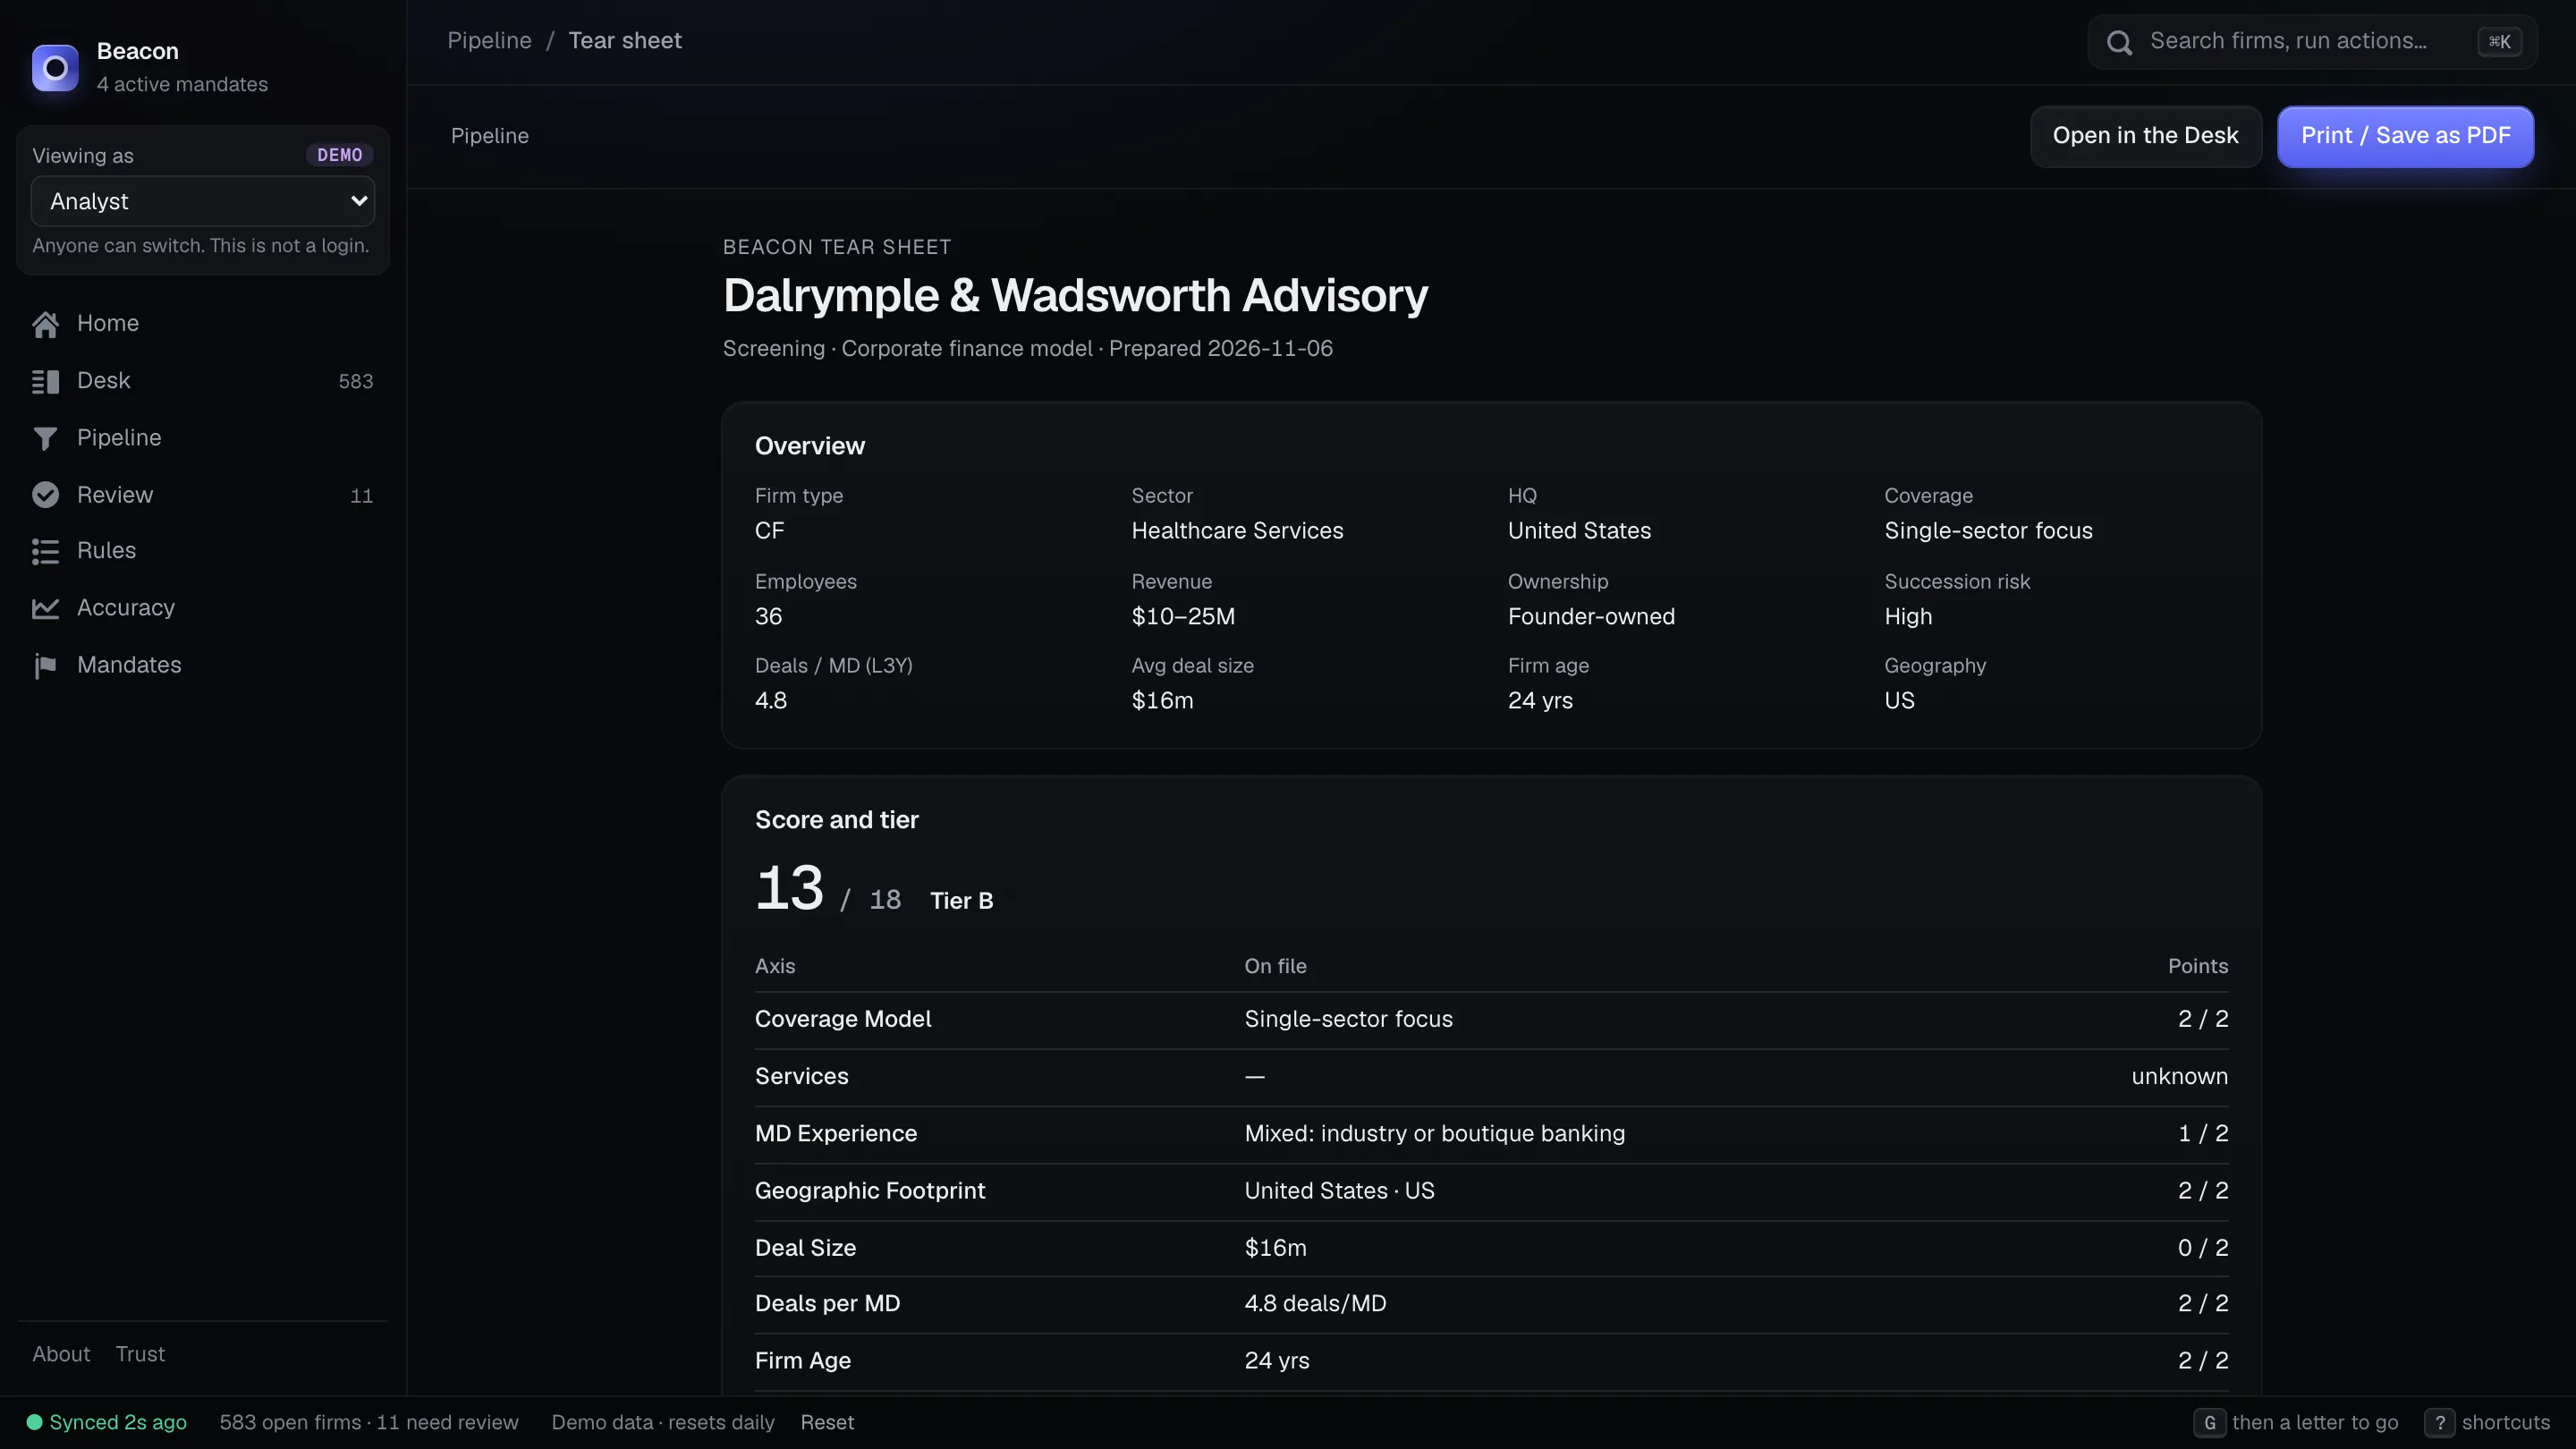
- Tear sheets. A printable one-page profile per firm: overview, score by axis, key evidence with its source and model, open conflicts and abstentions, signals and decision history.
- Lookalikes. "More like this" for any firm and for the approved targets, each match with the reasons it matched.
- Information barriers. A demo persona (analyst, deal-team lead, compliance). A restricted list is hidden from everyone but compliance on every read path, a mandate a viewer is not cleared for shows only its codename, and views are logged.
- An MCP server. A read-only Model Context Protocol endpoint lets an AI assistant search firms, read a firm's cited evidence and list screening rules, under the same barriers.
The port
| On Foundry | Now |
|---|---|
| Ontology Manager, 12 object types | One schema declaration, 18 object types and 18 named actions; the DDL, API validation, typed hooks and a generated ontology reference all derive from it |
| Generated SDK and its React hooks | Hooks with the same names over TanStack Query, so screens changed only their imports |
| Actions and Functions | Named actions, each validated and run in one transaction, and query functions, behind a handful of API routes on a Cloudflare Worker |
| AIP Logic | Claude extraction with a grounding check, recorded as fixtures; clustering behind a flag with a hard budget |
| Markings and permissions | A demo persona with a restricted list, need-to-know codenames and an access log, enforced on the server |
| Backend | Postgres: in-process PGlite for tests and local work, Neon in production; the same SQL runs on both |
The demo is open and writable. A single shared analyst can run every action, a nightly job restores the seeded world at 04:00 UTC, and a Reset button does the same on demand, throttled to once every five minutes; the reset is one transaction. The seed builds the history through the real actions, which makes it an end-to-end test as well as a demo. A pre-publish check fails the build if any file mentions the original employer, the licensed data vendors, the real firm names from the original data or the original rubric wording; its patterns are stored as salted hashes so the check itself gives nothing away.
The database enforces what the app never writes: required columns, foreign keys, one rule per predicate, and history tables (scores, decisions, findings) that refuse UPDATE and DELETE. The schema changes only through numbered SQL migrations, and the Worker refuses API requests while the database is behind the build. Action parameters are declared once and type both the client call and the server handler, and the screens reach the server through one documented data adapter, the seam a Foundry adapter would replace. Cloudflare Hyperdrive pools the Worker's database connections, which roughly halved the median API response (1.03 s to 0.54 s in ten calls from Los Angeles), and a daily check exercises the live demo an hour after the nightly reset.
Status
Ported in September 2026 and public under MIT since November. Over 1,100 unit and integration tests run against in-memory Postgres, 161 Playwright tests drive the app, and the evaluation runs on every CI build. Ten decision records explain the choices that matter. Everything on the live site is synthetic: firm names are generated from invented words, sources are mocks, market signals are invented news, and the captures here show one day's seeded history, which the next reset replaces.